OCP Global Summit: Amid Ecosystem Adoption, NVIDIA Opens Vera Rubin Architecture to Help Scale AI Factories Worldwide
At the Open Compute Project Global Summit, held at the San Jose McEnery Convention Center, NVIDIA announced a set of partnerships and contributions aimed at creating a common foundation for next-generation AI infrastructure. The company contributed key Vera Rubin rack and compute tray designs to OCP through its open MGX architecture, giving system builders a shared basis for developing AI factory infrastructure. Ian Buck, NVIDIA's vice president of hyperscale and high-performance computing, addressed the audience on how open infrastructure is becoming a critical ingredient for scaling AI factories worldwide. The announcements span three layers: the AI factory itself, the utility grid that powers it, and the rack-scale architecture at the heart of modern accelerated computing.
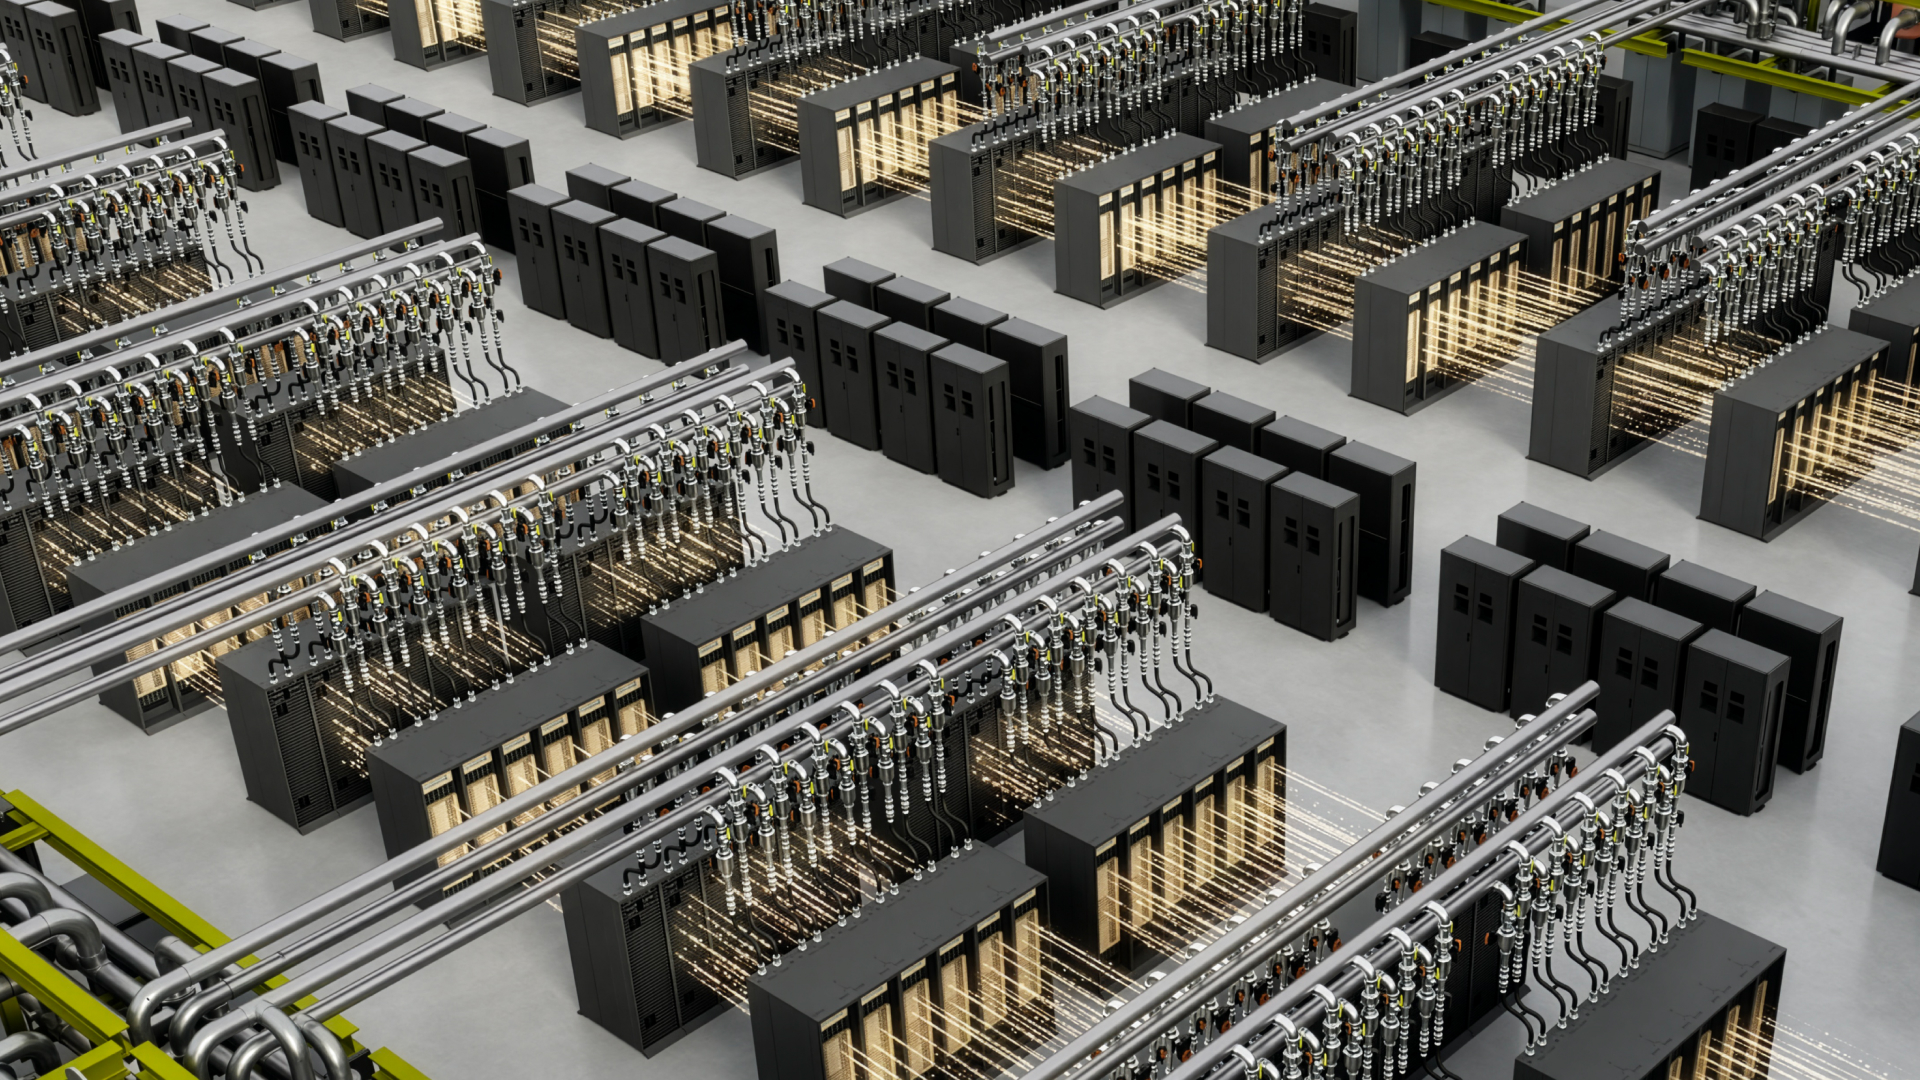
The hardware centerpiece is an update to the MGX rack specification. NVIDIA joined industry leaders in contributing to the third-generation MGX AI data center reference design through OCP's Open DC Initiative, combined with open liquid-cooling technologies the post calls MQD and MQDB. For Vera Rubin AI factories, the MGX 1.2 specification adds rack-scale blind-mate liquid cooling, interoperable rack-scale interconnect infrastructure, and a liquid-cooled 5,000A busbar intended for higher-power AI systems. It also brings native 19-inch equipment support and higher-density rack designs. Modularity expands with configurable I/O bays, fanless liquid-cooled compute trays, and standardized power and cooling interfaces. According to the announcement, the architecture supports rack deployments up to 250kW and improves assembly, test and service times to streamline manufacturing and field service.
A second rack design extends MGX beyond accelerated computing. The Vera CPU rack specification is described as a purpose-built platform for the agentic AI era, targeting tool calling, orchestration and sandboxed execution so AI agents can interact with applications, data and services in real time. Vera Rubin NVL72 remains the foundation for large-scale training and inference, while the Vera CPU rack shares the same rack-scale design principles that unite compute, networking, power and cooling. In practice, this split suggests NVIDIA is signaling that agent workloads have different infrastructure needs than training clusters: more CPU-side orchestration and isolation, less raw accelerator density. That framing is my reading of the stated use cases, not a claim from the company.
On the software side, NVIDIA expanded its DSX AI Factory platform with open source components. DSX OS is described as the open operating layer that turns the DSX architecture into coordinated, repeatable operations at scale. Four new components were announced. NVIDIA Config Manager automates switch configurations at scale, aiming for minimal to zero manual intervention. NVIDIA Cluster Readiness Engine stress-tests GPU clusters with real workload simulations to catch hardware problems before training begins, which the post frames as a way to avoid costly job crashes. NVIDIA Rack Management Service provides rack hardware abstraction and operations, treating racks as first-class units for firmware management. Cluster API Provider for NVIDIA Infrastructure Controller targets bare-metal deployment and tenant onboarding, turning raw AI hardware into production-ready clusters in hours instead of days. These components were developed from NVIDIA's experience running DGX Cloud and are meant to let cloud providers and software partners integrate AI factory capabilities into multi-tenant platforms. Developers can find them on the DSX AI Factory GitHub page.
Two open specifications were published alongside the announcements. The Open Data Center Specification v0.7, published by NVIDIA with AMD, Google and Meta, defines a unified blueprint for next-generation AI factory facility design covering power architecture, cooling infrastructure and physical layout. Separately, the OCP Grid Resilience Specification, published by Google, Meta, Microsoft and NVIDIA, specifies how large-scale AI infrastructure should behave during utility grid disturbances: stay connected, respond automatically, and restore to near-full load in under two seconds. Because these specifications sit under the NVIDIA DSX reference design, the post claims a validated, deployable implementation path from community standard to a running system. The practical effect, if vendors adopt them, is that equipment makers, colocation providers and operators can design against a shared target rather than waiting on proprietary customer specifications.
Power delivery drew several announcements. Visionbay unveiled plans for K-1, an AI factory platform built around an 800 VDC architecture and designed with future Vera Rubin deployments in mind, combining NVIDIA's 800 VDC reference architecture with power and thermal technologies from Vertiv. The rationale is that rising rack power densities make traditional low-voltage distribution harder to scale, requiring more copper, cabling and conversion equipment. K-1 is designed to phase in 800 VDC distribution where it helps most rather than forcing a full transition immediately, and centers on cluster-level power centers that centralize AC-to-DC conversion and push 800 VDC closer to compute. A likely trade-off is that 800 VDC adoption depends on facility-level coordination and supply-chain readiness, so phased designs like K-1 are an attempt to lower that barrier rather than eliminate it.
Networking saw three distinct developments. Meta is adopting NVIDIA Spectrum-6 102.4Tb/s Ethernet switches to build larger Vera Rubin AI factories on open networking. Spectrum-6 is said to double the switching capacity and per-lane bandwidth of Spectrum-4, providing a lossless Ethernet AI fabric at 200G per lane with performance isolation so one job's traffic does not slow another's. Meta's Spectrum-6-based switch, N-IceCube, fits into IcePack, Meta's 100T liquid-cooled rack, and runs FBOSS, Meta's open source network operating system contributed to OCP. FBOSS builds on the Switch Abstraction Interface, an OCP standard NVIDIA helped develop. The companies said these technologies support agentic AI factories of more than 100,000 GPUs training and serving large mixture-of-experts models. Spectrum-X Multiplane technology, enabled by Spectrum-6 switches and ConnectX-9 SuperNICs, distributes GPU traffic in hardware across up to eight independent network planes, scaling beyond 100,000 GPUs with fewer switch tiers, with traffic shifting to remaining planes when a component fails. Omar Baldonado, senior director of data center and AI networking at Meta, said the companies are making multiplane fabrics operationally scalable and noted that extending FBOSS to Spectrum ASICs lets Meta run the same software stack across its fabrics.
NVIDIA and Cisco announced plans for USFP, an optical pluggable transceiver module form factor. With roughly the same footprint as the widely adopted 200Gb/s-per-lane OSFP form factor, USFP targets 400Gb/s-per-lane networking, packing 16 full-duplex lanes with plans to scale to 32, and is claimed to deliver four times the bandwidth density of traditional 200Gb/s-per-lane pluggable optics with roughly 1.3x greater power efficiency. The aim is to connect more compute without adding network tiers. NVIDIA and Cisco are working with TE Connectivity and Amphenol on cages, connectors and modules, with plans to advance USFP through a community-led, multi-source effort.
Finally, NVIDIA and Google announced Falcon Transport support on future NVIDIA ConnectX-10 SuperNICs and BlueField DPUs. Falcon is a transport protocol for reliable data delivery over Ethernet, which can otherwise drop packets under congestion, and supports AI and storage workloads through multipath load balancing, programmable congestion control, hardware loss recovery and per-connection security. The collaboration combines NVIDIA hardware acceleration with DOCA software to implement Falcon, with NVIDIA and Google NICs communicating over a common transport while applications retain standard RDMA programming interfaces. The clear intent is to let large Ethernet AI fabrics keep bandwidth utilization and latency predictable as they grow, without forcing applications to adopt a new programming model.
Why it matters: This is primarily infrastructure news, but it directly shapes what system builders, cloud providers and platform teams can plan for. The MGX 1.2 contributions, the 800 VDC work and the two open specifications give hardware and facility vendors a common target, which could shorten design and procurement cycles for AI data centers. For developers, the more immediately usable items are the DSX AI Factory open source components: cluster validation, rack management and bare-metal provisioning are the operational chores that typically slow GPU capacity from becoming production clusters. Inference is that multi-vendor interoperability remains unproven until third parties ship against these specs, so teams evaluating them should treat the open standards as direction rather than a guarantee of drop-in compatibility.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
As AI factories grow from megawatts to gigawatts, building them takes more than advanced computing. Open standards are helping the industry scale AI infrastructure faster, more efficiently and more reliably. At the Open Compute Project (OCP) Global Summit, taking place in the San Jose McEnery Convention Center, NVIDIA announced new partnerships and contributions aimed at […]