[AINews] Xiaomi MiMo-V2.6-Pro 1T-A42B: the new top Open Weights model, trained for $3M
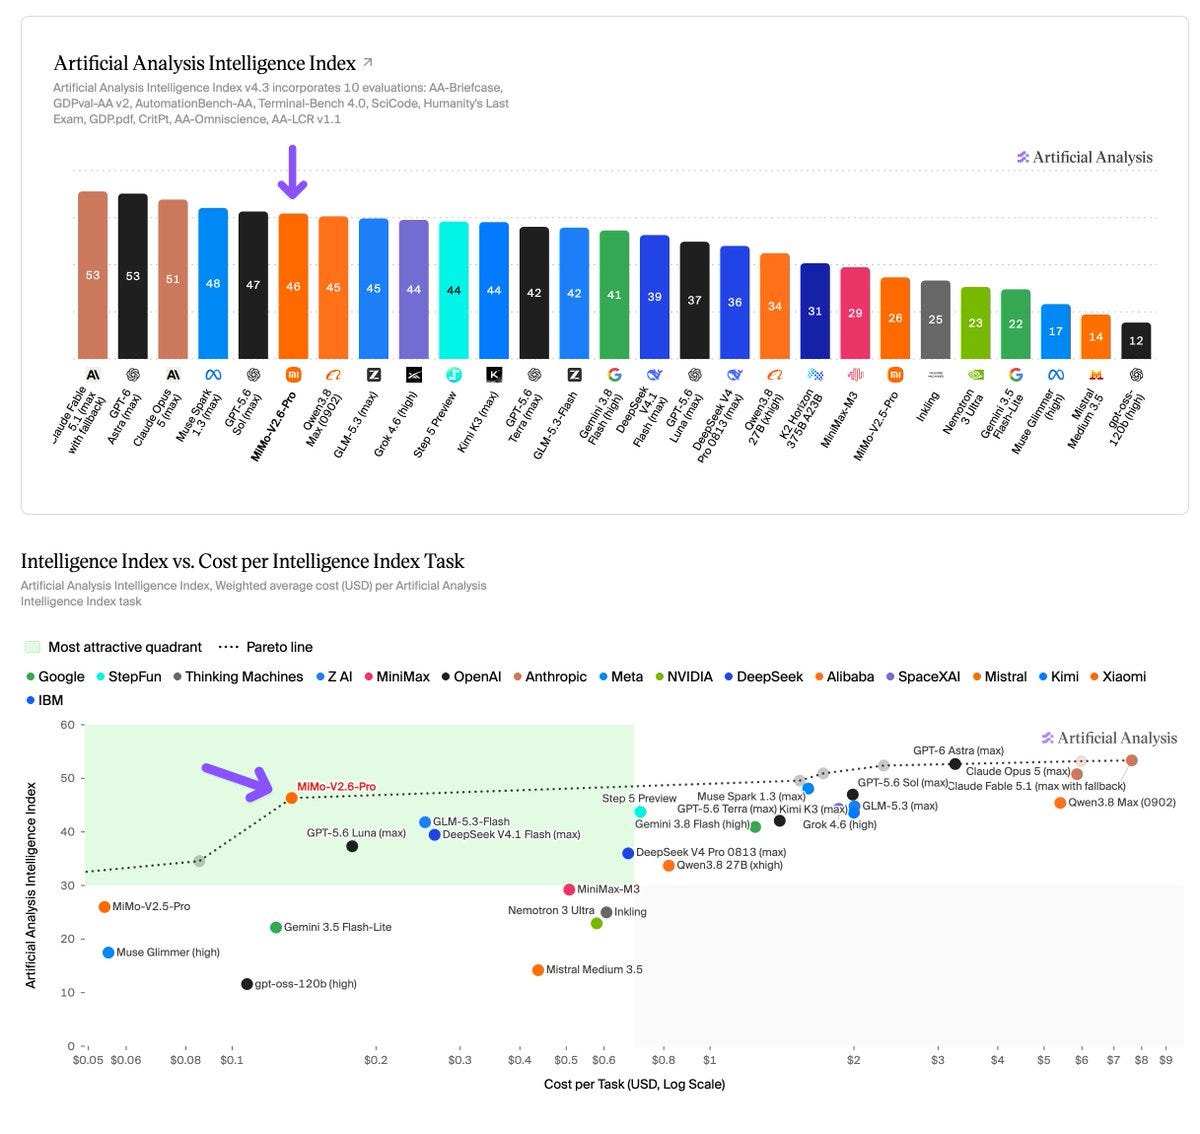
Xiaomi released MiMo-V2.6-Pro, an open weights model that Artificial Analysis says debuts as the top open-weights model on its Intelligence Index with a score of 46. The model has 1.02T total parameters and 42B active parameters, with pricing of $0.435 per million input tokens and $0.87 per million output tokens, according to Artificial Analysis.
Xiaomi described the MiMo-V2.6 series as including two natively omnimodal models. MiMo-V2.6-Pro is described as the company's most capable model to date, while MiMo-V2.6-Flash is positioned as balancing intelligence, efficiency and cost. Xiaomi also said it is rolling out MiMo-V2.6-Pro-UltraSpeed, which it says delivers up to 20x faster output speed at the same quality for users requiring extreme generation speed.
According to the technical report, Xiaomi scaled reinforcement learning compute along three axes: larger batches and higher throughput, with large batches on a fully asynchronous architecture, 1,568 samples per update, training at up to 1M context length, and 3.5 to 3.7B tokens per step; more tasks and richer environments, spanning coding, general agents, visual and cyber work mixed across several harnesses; and more grader compute, using relative comparison within each group for more precise and diverse reward signals on long-horizon RL tasks.
Xiaomi said the tooling, including environments, will be open sourced. The listed components include coding and software engineering recipes, dataset loader and rewards; the ARVO environment and training recipe for cyber and vulnerability reproduction; a general environment with tools and training recipe; a web-development environment and grading; music generation data preparation and scorer; composable mini-harnesses for agent configurations; and shared environment adapters. The complete 7k+ task datasets have not yet been released.
Xiaomi made news days earlier when Fuli Luo, a former DeepSeek engineer now at Xiaomi, began publishing final RL training runs live, showing an unusual amount of transparency in internal metrics.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
crowning a new Chinese frontier lab