Run multi-node inference workloads using Ray LLM Deep Learning Containers
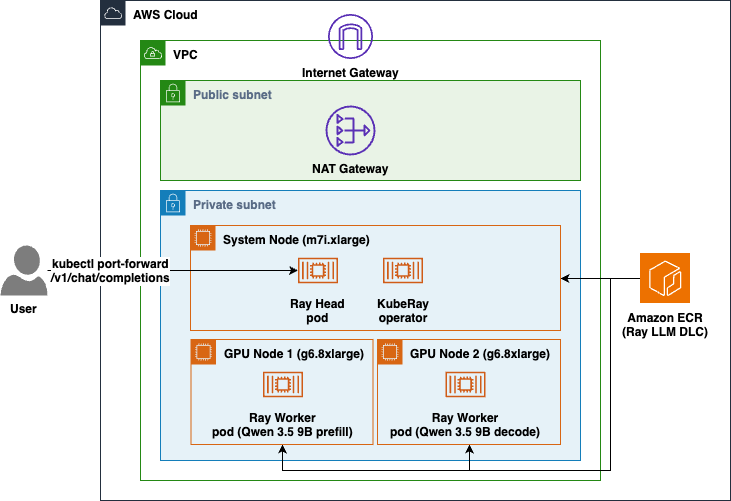
AWS published a walkthrough showing how to serve a single large language model across two GPU nodes on Amazon Elastic Kubernetes Service (EKS) using its multi-node Ray LLM Deep Learning Container (DLC). The deployment puts the prefill phase of inference on one GPU node and the decode phase on the other, with both sitting behind one OpenAI-compatible HTTP endpoint. The example model is Qwen/Qwen3.5-9B, and the accompanying code is available in a linked repository.
The container is the news here. AWS DLCs are pre-built, performance-optimized Docker images that bundle a framework, its dependencies and the GPU stack into a tested, patched combination. The Ray LLM DLC applies that model to distributed LLM serving: it ships vLLM as the inference engine, Ray Serve's HTTP layer as the serving front end, NVIDIA Inference Transfer Library (NIXL) for moving the KV cache between nodes, and the Elastic Fabric Adapter (EFA) stack — libfabric and aws-ofi-nccl — for high-bandwidth node-to-node communication. All components are validated together before each release, so there is no version drift between the CUDA runtime, the framework and the serving layer, and security patches are applied at build time.
The reason to split prefill and decode is resource contention. Prefill processes the whole input prompt in parallel and builds the key-value cache; it is compute bound. Decode generates the response a token at a time, reading and extending that cache; it is bound by memory bandwidth. On a shared GPU, bursty prefill work interferes with the steady, latency-sensitive decode work, so a long prompt can stall token generation for requests already in progress. Disaggregation places the two phases on separate nodes, letting each be sized and scaled independently. The trade-off is that the KV cache built during prefill must be handed to the decode node, which is why the interconnect matters so much.
The reference architecture is straightforward to describe. An EKS cluster runs inside a VPC, with nodes in private subnets and outbound access through a NAT Gateway. A CPU system node (m7i.xlarge) hosts system workloads, the KubeRay operator and a CPU-only Ray head pod. Two GPU worker nodes (g6.8xlarge) run the Ray workers, one for prefill and one for decode, pulling the Ray LLM DLC from Amazon Elastic Container Registry. KubeRay watches the applied RayService and wires the head-to-worker join automatically; Ray Serve then places the prefill and decode deployments on the two GPU workers. The KV cache flows from prefill to decode over NIXL using EFA through NIXL's libfabric backend. The GPU node group is pinned to a single Availability Zone, because EFA cannot cross AZs.
Configuration lives in a block of YAML rather than application code. The serveConfigV2 block in manifest/rayservice.yaml calls the built-in helper build_pd_openai_app, which takes a prefill_config and a decode_config and connects the KV-cache transfer between them. Both configs reference the same model, set max_model_len to 4096, use bfloat16 precision, allow vLLM to claim 90 percent of GPU memory, and set enforce_eager to true to skip CUDA graph capture and reduce peak GPU memory. Each side uses NixlConnector with kv_role kv_both and a distinct engine_id so the two phases can be told apart. Working from these settings, the critical line appears to be kv_connector_extra_config with backends set to LIBFABRIC: without it, NIXL falls back to UCX, which the post says runs at TCP speed even on EFA — and the fallback is silent.
That silence is worth designing around. NIXL does not raise an error when it cannot use libfabric, so the post recommends grepping worker logs for the instantiated backend and checking the vpc.amazonaws.com/efa count per node. A prebuilt NVIDIA Collective Communications Library benchmark at /usr/local/bin/all_reduce_perf is included for a cross-node bandwidth number. A single reported performance figure stands out: with the described cache configuration, model-weight loading for Qwen3.5-9B on a g6.8xlarge drops from roughly 145 seconds to about 2 seconds on restart.
The pod spec has its own constraints. The head pod requests zero GPUs and is pinned to the system node group. Each worker requests one GPU and one EFA interface, targets nodes labeled role=gpu-worker, and runs privileged because NIXL registers CUDA VRAM with the EFA NIC — the IPC_LOCK capability alone is not enough. Workers set FI_PROVIDER=efa, read VLLM_HOST_IP from the pod IP and mount a shared-memory volume, with memory limits set well above the roughly 18 GiB checkpoint so the OS page cache can hold it.
Deployment is scripted in four idempotent steps sharing one env.sh file. Creating the EKS cluster with its CPU system node group takes 15 to 20 minutes on a fresh run. Adding the GPU node group — two g6.8xlarge instances with EFA enabled, pinned to one AZ and labeled for the Ray workers — takes about 5 to 20 minutes, usually longer the first time, and also installs the EFA device plugin that advertises the EFA resource on each node. Installing the KubeRay operator via Helm takes 1 to 2 minutes and is pinned to the system node group to keep GPUs free for inference. Applying the RayService then creates the head and two worker pods and brings up the prefill and decode deployments; because each node loads the model, that step takes several minutes. Prerequisites include an AWS account with billing enabled, quota for two g6.8xlarge instances (at least 64 vCPU) in the target Region, and the AWS CLI, kubectl, eksctl, Helm and envsubst utilities.
Once the Serve app reports RUNNING, KubeRay exposes a stable service that can be reached by port-forwarding port 8000. Listing models and sending a standard chat-completion request require no custom schema, and teardown runs the four scripts in reverse order to avoid ongoing charges. The post notes that the same multi-node patterns extend to tensor and pipeline parallelism for models too large for one instance, data parallelism for throughput, and decode replica scaling.
Why it matters: teams that already run vLLM on EKS get a maintained container that removes the job of hand-assembling CUDA, Ray, NIXL and EFA versions, which in practice is where much multi-node serving effort goes. The specific gain is prefill/decode disaggregation behind a familiar OpenAI-compatible endpoint, letting prefill and decode scale separately; my reading is that this suits RAG, summarization and agentic workloads with long prompts, while the single-AZ pin, privileged pods and the silent UCX fallback are the operational details to plan for. Expect the value to hinge on EFA actually being in use, since a quiet TCP-speed fallback would quietly erase the benefit.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
Learn how to deploy one large language model across two GPU nodes on Amazon EKS using the multi-node Ray LLM Deep Learning Containers, with separate prefill and decode nodes behind one OpenAI-compatible endpoint. The pre-built container ships the full inference stack, so you configure the deployment instead of assembling it.