Introducing Kimi K3.1 Pro
Moonshot has made Kimi K3.1 Pro available through the Kimi API as of today. The model is not yet open weights, but the company has committed to publishing full model weights by November 4, 2026 — a date far enough out that users of the API can treat the weights release as a future milestone rather than an immediate option. A Highspeed variant is also offered, running 2-3x faster at double the price, with input token cache hits priced the same as the standard tier.
Pricing in US dollars is $2.00 per million input tokens and $10.00 per million output tokens. That puts it level with GPT-6.1 Sol and at half the cost of Claude Opus 5.5, according to the announcement.
On evaluation, Moonshot's own benchmarks place Kimi K3.1 Pro roughly level with Opus 5.5 and GPT-6 Astra, winning a few benchmarks and coming close on others. Independent scoring from Artificial Analysis put Kimi at 55, ahead of Claude Fable 5.1, GPT-6 Astra and Gemini 4 Argon, all at 53, and behind only Claude Opus 5.5 at 58. The notable point is that this is the first time a soon-to-be open weight model has scored this highly against frontier competition — a shift worth watching for teams that weigh open licensing against raw capability.
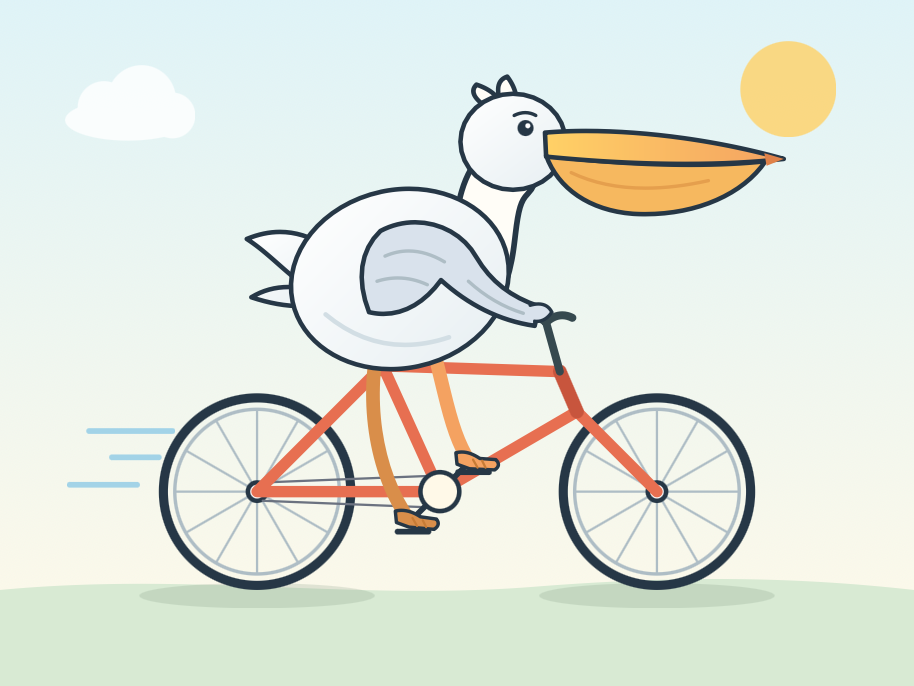
Simon Willison tested the model through the Moonshot API using the openai endpoint command he added to LLM 0.32 in August: llm openai endpoint https://api.moonshot.ai/v1 --key kimi -m kimi-k3.1-pro "Generate an SVG of a pelican riding a bicycle" --responses -o reasoning_effort low, saving stdout and stderr to files. Because that command can hit any OpenAI-compatible endpoint but does not log results, the extra redirects capture both the output and the reasoning trace. He generated pelicans at all three reasoning levels the model supports — low, medium and max — and ran fresh comparisons against Kimi K3 at the same levels.
The OpenAI-compatible endpoint matters for developers: it means existing tooling built around the OpenAI chat or responses API can point at Moonshot with a base URL change and an API key, without a dedicated SDK. The reasoning_effort parameter exposes the three tiers as a dial, letting teams trade latency and cost against quality per request. In practice, that kind of tiering suits mixed workloads — cheap low-effort calls for routine generation and max-effort calls for harder reasoning — and the Highspeed tier adds a separate axis for latency-sensitive products. A likely trade-off is that Highspeed doubles per-token cost, so it only pays off where response time drives user experience or where cached input dominates the bill.
Why it matters: teams comparing frontier models now have a cheaper option that independent scoring places near the top, at half the price of Claude Opus 5.5 on input and output. The OpenAI-compatible API lowers switching cost to a configuration change, which makes it practical to benchmark against existing providers. The promise of open weights by November 2026, if kept, would let organizations self-host a near-frontier model — an inference worth flagging rather than a certainty.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
Introducing Kimi K3.1 Pro Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026". They're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same). The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5. Moonshot's own benchmarks show Kimi as approximately