5 useful things you'll learn in my new post-training textbook (shipping now!)
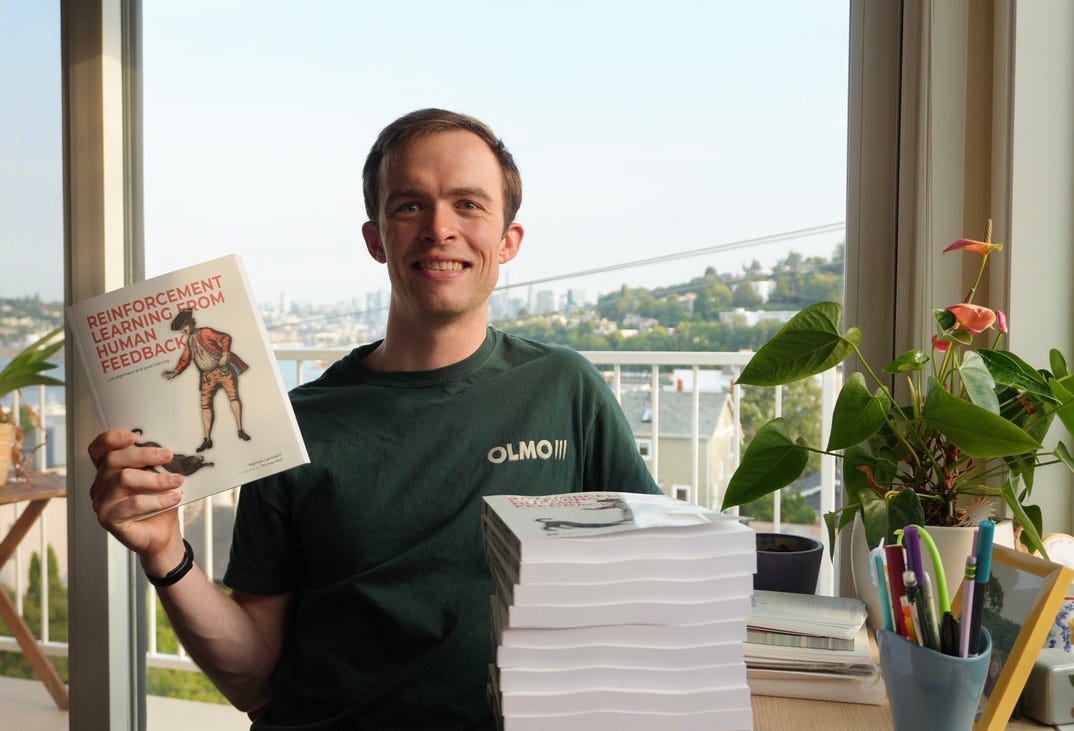
The post-training textbook Reinforcement Learning from Human Feedback: Aligning and Post-training LLMs is finished and published by Manning, the author announced. It is shipping from Manning and Amazon US now, and from Amazon UK in October. It is also freely available online and comes with a 12-hour course (slides and video on YouTube), a code-base with suggested exercises, and model completion comparisons. It is 50% off until August 19th on Manning with the code PBLambert.
The book began as a website documenting post-training methods that the author said had little online material explaining them, including rejection sampling, outcome reward models, and character training. The author describes it as not a beginner book, tailored to someone who has finished a bachelor's degree in computer science, and says some older Interconnects blog posts were reworked into it.
The author lists five things readers will learn. First, intuitions for how RL algorithms change model outputs; roughly 25% of the book by word or page count is about RL, covering the policy-gradient theorem, PPO, GRPO, GSPO, and CISPO, among other algorithms. Second, an understanding of factors facing new RL systems and algorithms, including how off-policy data is, training-inference mismatch, throughput, and asynchronous RL with separate GPUs for learners and actors; it covers loss aggregation, which the author says spawned DAPO and Dr. GRPO, and truncated importance sampling.
Third, the histories leading to modern post-training, described across three eras: RL on preferences generally until about 2018, applying it to language models from 2019 to 2022, and exploiting examples set by ChatGPT from 2023 on. Fourth, a chapter on distillation, which the author says explains industry-standard ways LLM outputs train downstream models and the transition from 2015 knowledge distillation literature to multi-teacher on-policy distillation of models such as Xiaomi MiMo-V2-Flash and DeepSeek V4. Fifth, a survey of other challenges in post-training, including over-optimization, regularization, evaluation, and character training.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
After a few long years of finding time to document my lessons from training open models, my post-training book is done!