Fine-tune a search agent with multi-turn RL on Amazon SageMaker AI
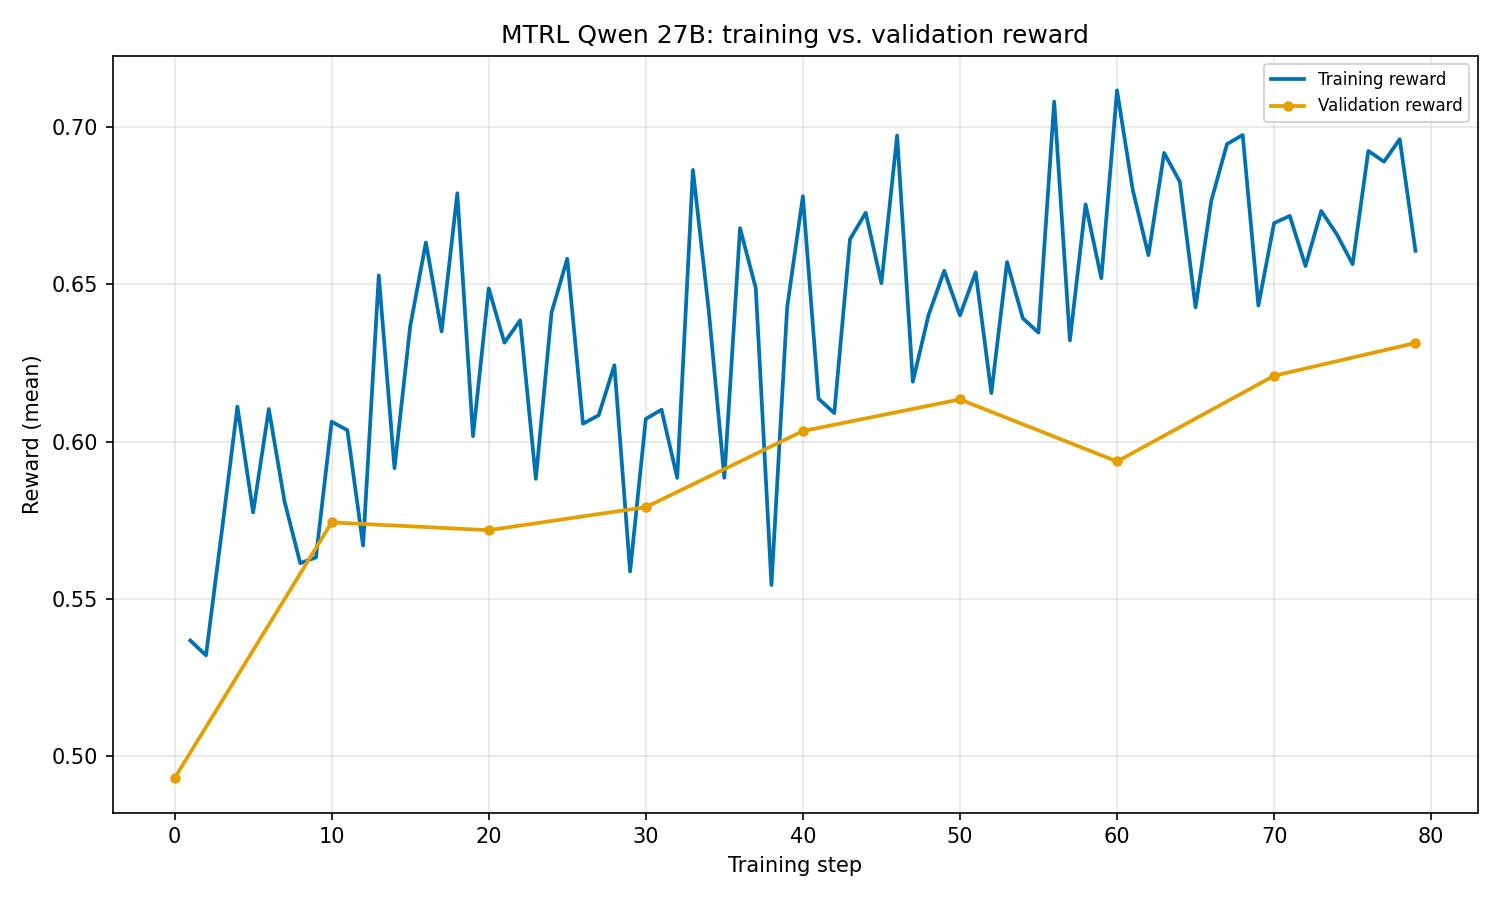
AWS published a report on fine-tuning a search agent with multi-turn reinforcement learning (MTRL) on Amazon SageMaker AI, using a Qwen3.6-27B model supported in the US West (Oregon) Region (us-west-2). The setup used an enterprise search environment exposing two tools: lexical BM25 search for exact keyword matches and vector search for semantic or conceptual queries, with a limit on the number of turns.
MTRL frames an agentic task as a sequence of decisions, uses multi-turn rollouts to generate training data, and optimizes the model with policy gradient algorithms. AWS lists a modular agent-environment interface, serverless per-token execution, asynchronous rollout with bounded off-policy staleness, a native algorithm library (PPO, CISPO, IS losses paired with GRPO, GRPO pass@k, RLOO and others), resumable training, trajectory and reward observability in MLflow, and evaluation jobs reporting reward, pass@k and trajectory metrics.
The reward function was nDCG@10 (Normalized Discounted Cumulative Gain at rank 10), applied at the trajectory level. When the agent hit the maximum number of turns or maximum sampling tokens in a single turn, a reward of -1 was assigned. Training data came from datasets including FRAMES, BRIGHT, Enterprise RAG, ESCI, Musique and MLQA, with 5 percent of training instances reserved as validation. Testing used FreshStack, WixQA, BrowseComp-Plus and Wands. Only three hyperparameters were changed from defaults: max_epochs (1), global_batch_size (128) and rollout_max_concurrency (32), launched through the MultiTurnRLTrainer SDK.
AWS reported improvements on three of four held-out benchmarks: WixQA nDCG@10 rose from 0.5725 to 0.6781 (+18.4 percent), Wands from 0.5762 to 0.6112 (+6 percent), and BrowseComp-Plus from 0.5136 to 0.6354 (+23.7 percent), with a slight regression on FreshStack (0.4112 to 0.4089). On BrowseComp-Plus the failure rate fell from 22.89 percent to 0.68 percent. AWS also noted the MTRL service has a default 24-hour time limit, adjustable through the CreateJob JSON schema, and that training can resume from a checkpoint after a stoppage or timeout.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
Fine-tuning teaches a small search agent your tools and environment, giving it the reliability of a frontier model at lower latency and cost. In this post, we fine-tune an LLM-powered search agent with multi-turn reinforcement learning (MTRL) on Amazon SageMaker AI and share the gains we measured in retrieval quality and reliability.