Aligning LLM-as-a-Judge with Human Preferences
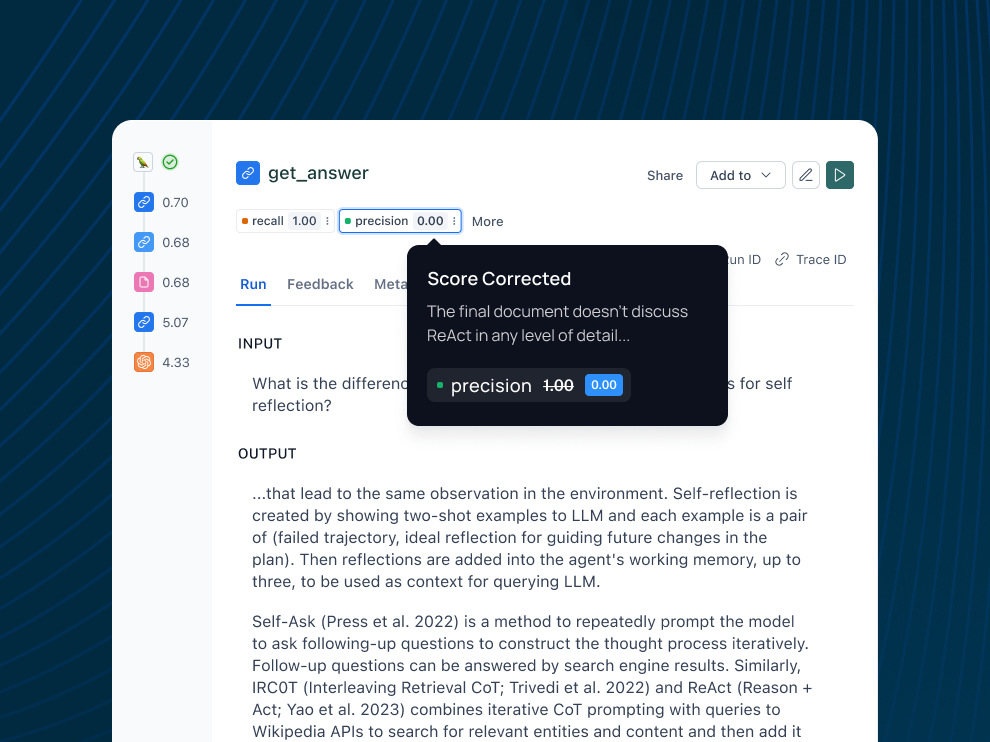
LangChain announced a self-improving evaluator capability in LangSmith designed to align LLM-as-a-Judge evaluations with human preferences, according to a company blog post.
The feature stores human corrections to LLM-as-a-Judge outputs as few-shot examples. These examples are then fed back into the evaluator prompt in future iterations. Users set up an LLM-as-a-Judge evaluator for online or offline use, the evaluator leaves feedback on generated outputs, and users can make corrections natively in the LangSmith interface. Corrections are stored as few-shot examples, and explanations can optionally be added. The next time the evaluator runs, it uses those stored examples to inform its generation.
LangChain stated the goal is to make it easier to create LLM-as-a-Judge evaluators that reflect user preferences without prompt engineering and to have them adapt over time. The blog post cited the rise of LLM-as-a-Judge evaluators plus motivating research on few-shot learning and a Berkeley paper by Shreya Shankar titled "Who Validates the Validators? Aligning LLM-Assisted Evaluation of LLM Outputs with Human Preferences." LangChain said the paper proposed a different solution but helped motivate using feedback collection to programmatically align LLM evaluations with human preferences.
The post described LLM applications producing natural language outputs that are difficult to judge with hard-coded rules, giving examples such as conciseness or correctness relative to a reference output. LLM-as-a-Judge passes generated output and other information to a separate LLM for judging. LangChain said this raises the need for additional prompt engineering to ensure the judge performs well. Use cases cited include detecting RAG hallucinations, RAG correctness, and toxic or inappropriate answers, across online and offline evaluation. LangChain also mentioned working with teams including Elastic and Rakuten on evaluation. A technical walkthrough and free LangSmith signup were referenced.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
Deep dive into self-improving evaluators in LangSmith, motivated by the rise of LLM-as-a-Judge evaluators plus research on few-shot learning and aligning human preferences.