Language Models for Text Classification: From Bag-of-Words to Jev
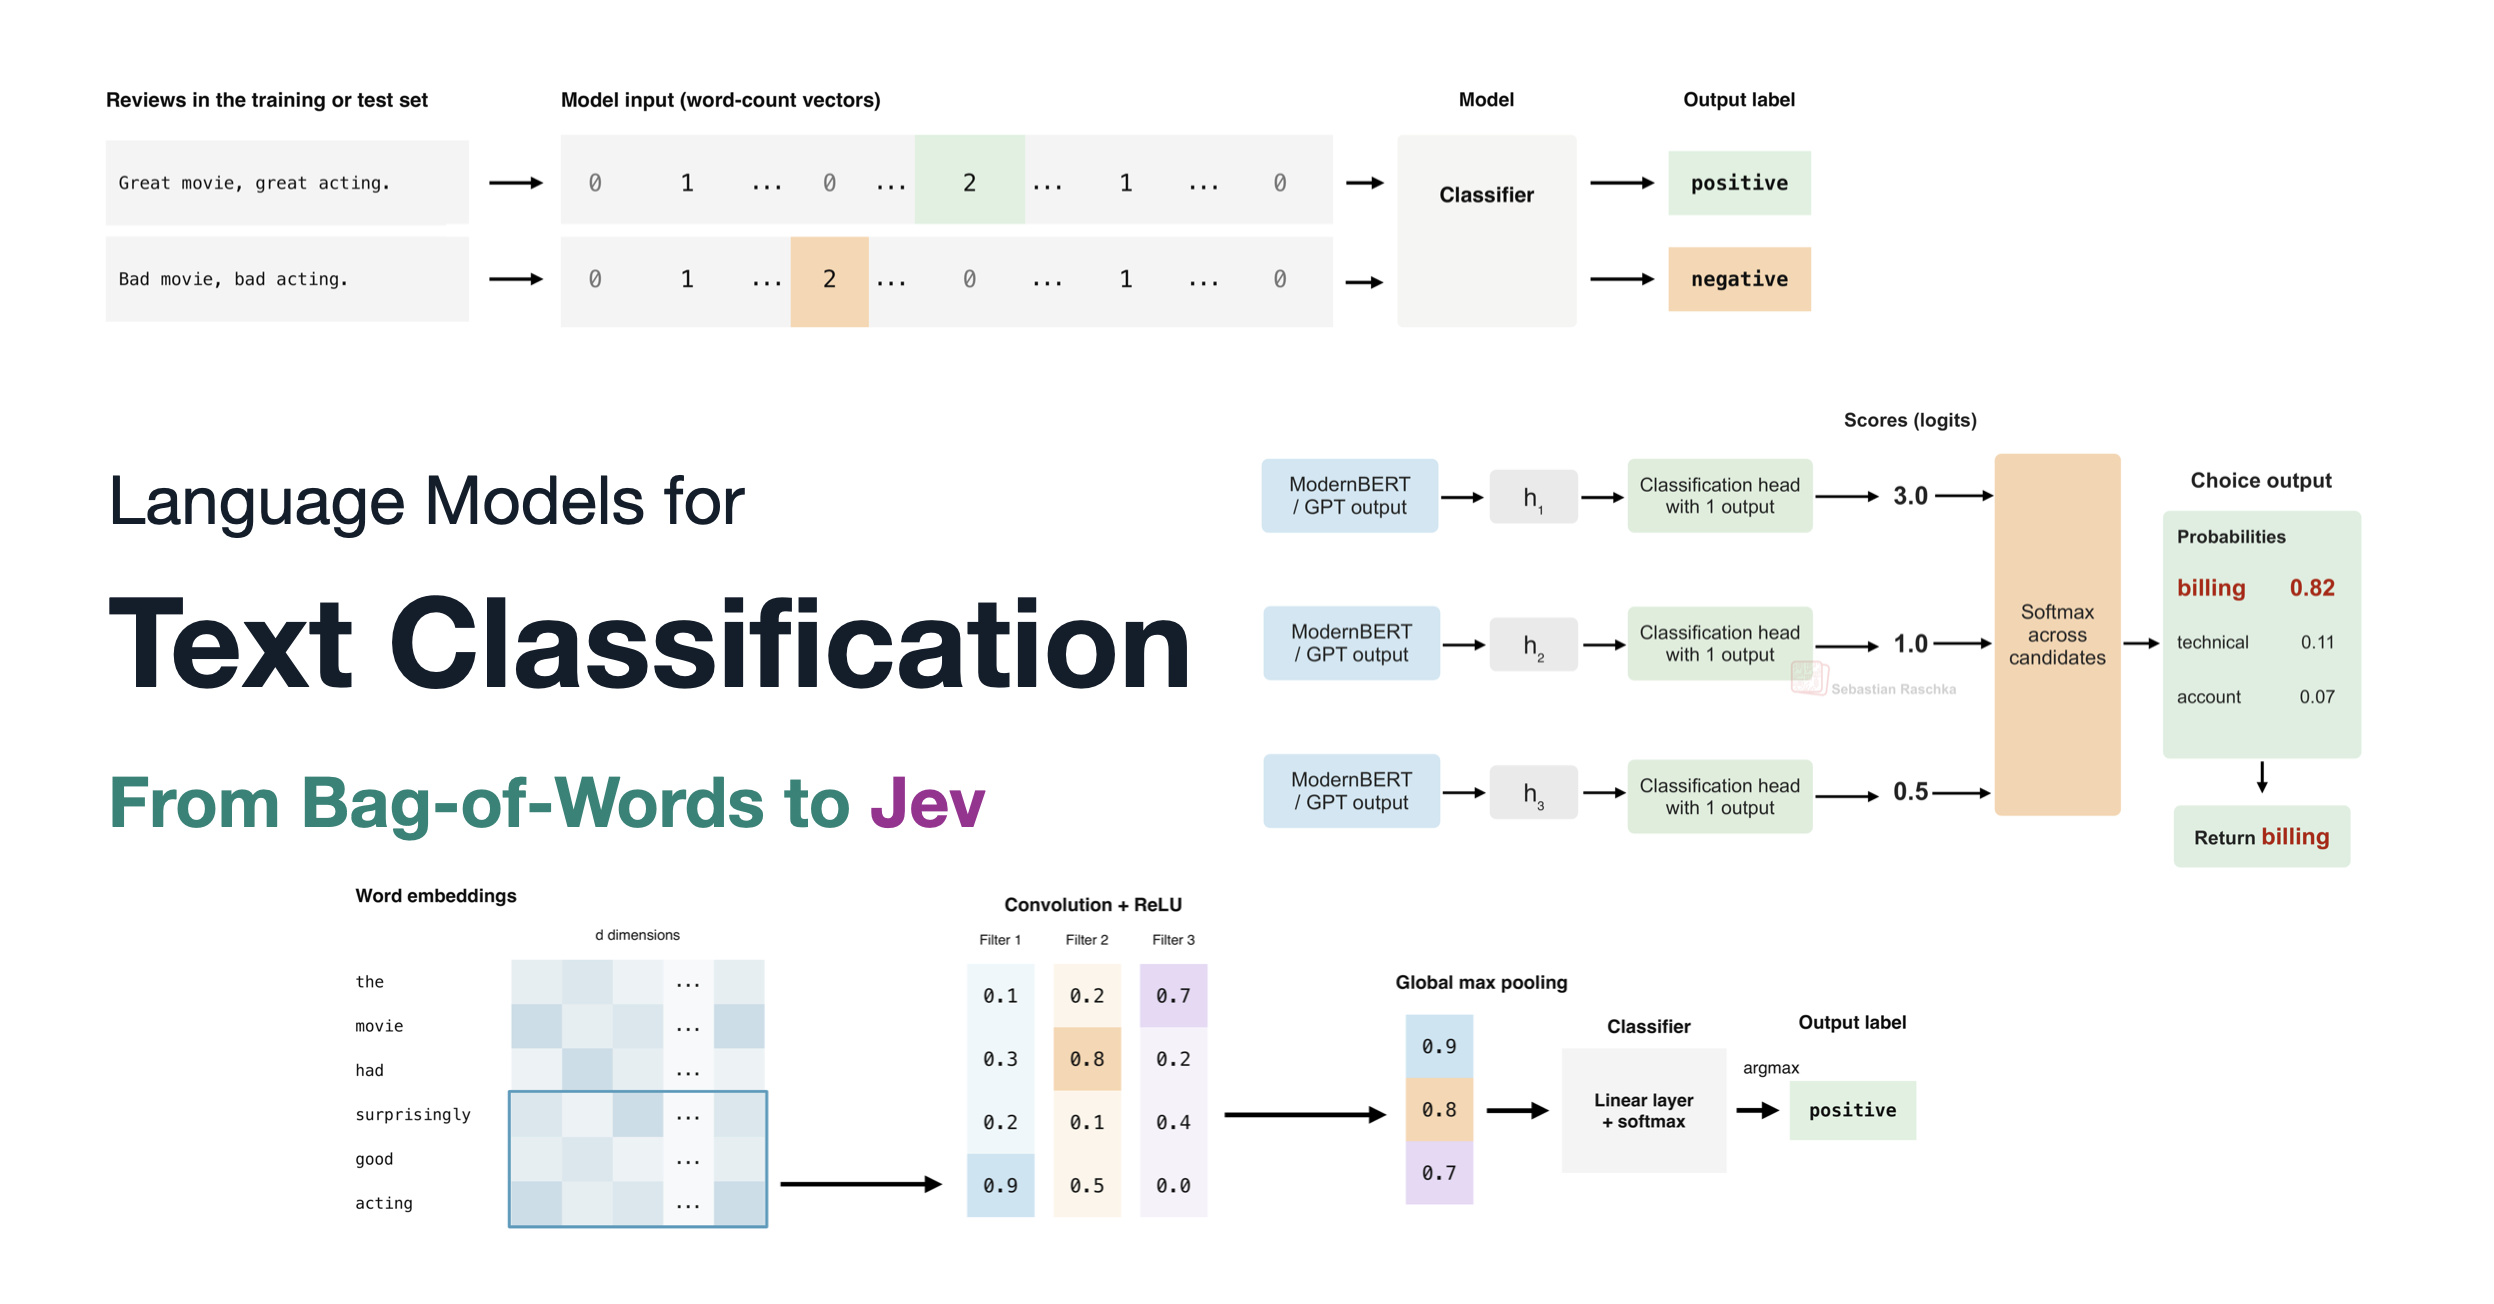
Jev, a recently released AI model built for classification tasks, has become a talking phenomenon in technical communities over the past two weeks, according to a new long-form technical article from Ahead of AI. The author, who states no affiliation with Jev and no free access to it, traces the history of language models for decision-making to explain the model's appeal, and describes a personal shift from initial skepticism to finding that it works better than expected. The piece is framed as technical context rather than a product endorsement, and some of its account of how Jev works is explicitly labeled an educated guess.
The article's central argument is that Jev occupies a middle position. State-of-the-art GPT models and open-weight LLMs can perform the same classification tasks Jev handles, and can do far more general decision-making besides, but Jev's stated advantage is speed and cost on classification. At the other end, for a narrow, well-defined problem, a special-purpose classifier will likely match or beat Jev on quality, speed and price. Jev's selling point is that it generalizes across tasks in a way task-specific models do not.
The historical tour starts with bag-of-words. In that approach, a vocabulary is built from all unique words in the training set, optionally with stopwords removed, and every document becomes a fixed-length count vector over that vocabulary, regardless of whether it holds ten words or 300,000. Most entries are zero. Normalization schemes such as TF-IDF can replace raw counts. Classic classifiers, including naive Bayes, logistic regression, SVMs, random forests and XGBoost, then learn weights tying words and counts to labels. The method is cheap and works when individual words carry strong signal, which is why it powered applications from news categorization to spam filtering; the article notes that Gmail's original spam filter is said to have used naive Bayes with bag-of-words. Its structural weakness is lost word order: the article points out that two sentences with the same words in opposite order produce identical vectors. N-grams can preserve some local order at the cost of a larger vocabulary. The author still treats bag-of-words plus logistic regression as a default baseline, reporting about 89.9% accuracy on a balanced IMDb movie-review split.
Dense word embeddings, whether learned externally via Word2Vec or GloVe or inside the network, represent single words as vectors and are context-independent at lookup, so "bank" looks the same in river and financial senses. Recurrent networks read one word at a time, combining each embedding with a hidden state summarizing prior text, which makes order matter and allows arbitrary input length. Variants include LSTMs from 1997, GRUs from 2014 and xLSTM from 2024; state-space models borrow the fixed-size sequential state idea. The article reports that a from-scratch LSTM reached only 85.66% on the same IMDb task, with training accuracy suggesting overfitting, while pretraining then fine-tuning, as in ULMFiT in 2018, reached 95.4%. Convolutional filters over windows of adjacent embeddings offer parallelism instead of sequential dependency; the author's text CNN reached about 90.07%, though results are architecture-dependent.
Transformers arrived in 2017 with Attention Is All You Need. Encoder-style models such as BERT are natural classifiers, using a classification token at the first position that can be fine-tuned on a target dataset; ModernBERT, a 2024 refresh, reaches roughly 95% on IMDb with little tuning effort in the author's tests. Decoder-style GPT models can classify zero- and few-shot as an emergent ability, and can also be fine-tuned or prompted for classification.
In practice, the trade-off for teams is a three-way choice: task-specific models for maximum efficiency on one fixed problem, large general LLMs for flexibility and reasoning, and Jev in between for many classification jobs at lower latency and cost. A likely caveat, in my reading, is that speed and price claims matter most at volume, so buyers should benchmark on their own labeled data before replacing tuned baselines.
Why it matters: product and engineering teams deciding how to route classification work now have a third option between bespoke classifiers and expensive general LLMs, and the article's numbers on cheap baselines are a reminder to test those first. Developers should treat the cost and latency edge as the claim to verify, since quality on narrow tasks may still favor small purpose-built models. My inference is that a reasonable first step is a bag-of-words or fine-tuned encoder baseline, measured against Jev on the same data.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
A Visual Guide to RNNs, CNNs, Transformers, and Calibration, with Hands-On Experiments on Accuracy and Efficiency