Controlling Reasoning Effort in LLMs
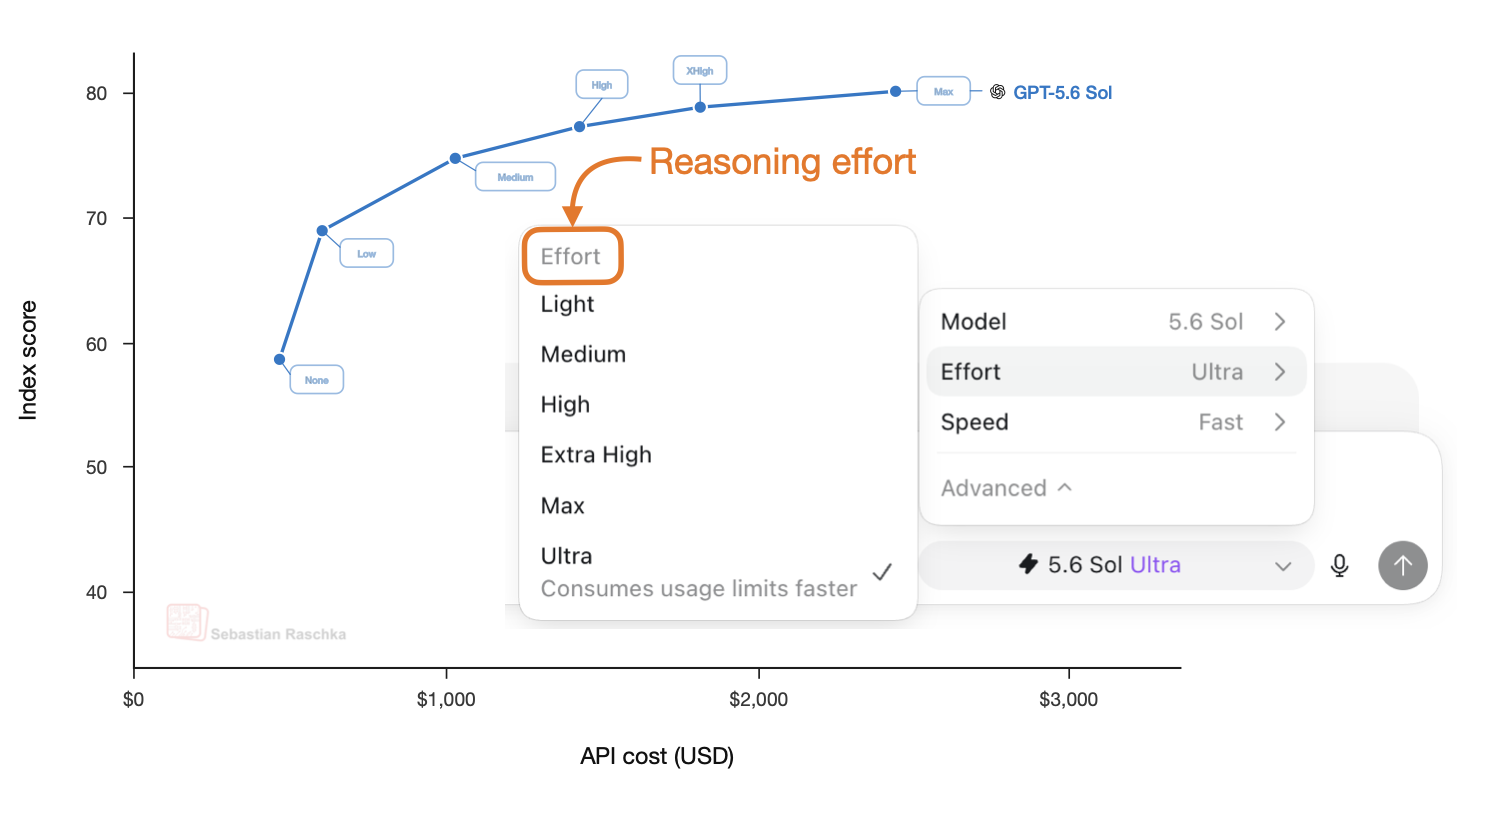
Ahead of AI has published an explainer on how reasoning models are trained to support multiple reasoning-effort modes, prompted by OpenAI's release last week of the GPT-5.6 model family. That family arrives in three sizes, each exposing roughly five or six effort settings; in the Codex interface shown in the article, the GPT-5.6 Sol model offers six levels running from Light to Ultra. Benchmark numbers for Ultra were not yet available, though the author expects them to land close to Max, since Ultra uses a similar effort level but speeds the work up with four subagents. The article sets out to explain how a model can be built with several effort modes rather than just one, treating the GPT-5.6 settings as the reference example.
The piece opens with a definitional point that matters for anyone reading model cards. In AI research, "reasoning model" does not mean a system that reasons the way people do. It means a model that emits an intermediate reasoning trace before its final answer: an explicit step-by-step working that precedes the response the user sees, in contrast to a conventional LLM that goes straight to an answer.
The article then frames the two levers for improving task performance. Training scaling means spending more compute during training, and the recipe that popularized reasoning models is reinforcement learning with verifiable rewards, or RLVR. It was detailed in DeepSeek-R1, which landed roughly four months after OpenAI's o1. RLVR works by rewarding correctness on domains where an answer can be checked automatically: math, where symbolic tools such as SymPy or WolframAlpha can verify a result, and code, where compilers, unit tests or platforms like LeetCode can. The reward is essentially binary, zero for wrong and one for right, plus a format component. Notably, the reasoning trace itself did not drive training in DeepSeek-R1; the paper reported that using the intermediate response information was not helpful, so it was dropped. Whether to fold reasoning traces into the training signal through process reward models remains an active research question.
A striking result is that output-only rewards were enough for the model to learn to work through problems, backtrack and correct itself. The article calls these self-corrections "Aha" moments. It also credits the surrounding literature: Kimi K1.5 appeared on arXiv on the same day as DeepSeek-R1, 22 January 2025, and the term RLVR had already been coined two months earlier in Tülu 3. DeepSeek-R1 stands out because it showed reasoning behavior can emerge from pure reinforcement learning. Its R1-Zero variant applied RLVR directly to the pretrained base model with no supervised fine-tuning, whereas Tülu 3 and Kimi K1.5 put RL on top of an SFT model. R1-Zero is weaker than R1, but it served as proof of concept that RLVR alone can teach a model to generate and use reasoning traces. The full R1 pipeline is multi-stage and more involved. The article estimates that most of today's LLMs are effectively reasoning models, trained in a similar fashion with some form of RLVR.
The second lever is inference scaling: spending more compute at usage time rather than training time. Training with RLVR already implies some of this, because reasoning models emit more tokens than conventional LLMs on the same prompt. Output length can be tuned further through effort levels. Beyond that sit techniques like self-consistency, commonly implemented as majority voting over multiple samples of the same query, which can be layered on top of a reasoning model; the article cites DeepSeekMath-V2 as a case where heavy inference scaling was applied to a math-specialized reasoning model to reach strong results on olympiad-style problems.
On the familiar think tags, the article is blunt: they are cosmetic. The delimiters mark where a reasoning trace starts and ends so a training pipeline or user interface can separate it from the final answer and optionally hide it, as ChatGPT and Codex typically do. They do not confer reasoning ability, the same model trained without them would likely score similarly on benchmarks, and any other pair of delimiters would serve. Implementation usually comes through a format reward added to RLVR, so DeepSeek-R1's total reward was accuracy plus format, with the format term a simple rule-based check that reasoning sits inside the tags.
The first generation of reasoning models had no off switch. R1, for example, tends to produce verbose output with many tokens even for trivial prompts, and offered no built-in way to disable reasoning. Hybrid models changed that. Qwen3 can behave as an ordinary instruction-tuned model or a reasoning model on demand, controlled through the tokenizer via enable_thinking=True or False. Setting it false effectively prepends an empty think section to the assistant response, so the model proceeds straight to the answer. The Qwen3 technical report describes how this is trained: after long-chain-of-thought SFT and reasoning RL, a "Thinking Mode Fusion" SFT stage shows the model both thinking and non-thinking examples, with /think and /no_think flags, and a later general RL stage reinforces the format. The flags are a soft switch; the tokenizer-level setting that force-inserts the empty tag is a hard one. This toggle is essentially a simplified forerunner of today's effort levels.
On how effort settings actually work, OpenAI has not published details for GPT-5.6. Evidence comes from the open-source gpt-oss models, where effort is toggled with a system prompt line reading "Reasoning effort: low/medium/high" that is prepended to each prompt through the chat template. Response length and accuracy move with that setting, and the article presumes GPT-5.6 works similarly, with a UI menu choice mapping to a system prompt. A caveat follows from the scaling curves: effort correlates with token usage, and token usage with accuracy, but returns diminish. The GPT-5.6 Sol data shows performance saturating at the top and increasing reasoning budgets becoming uneconomical. The article also cites this week's open-weight Inkling release from Thinking Machine Labs and its technical report as a concrete example: Inkling sweeps a continuous effort value between 0.2 and 0.99, with higher effort generally producing longer responses and higher benchmark scores, though gains turn uneven at the top end.
The article sketches two plausible training routes, noting these are possibilities rather than confirmed descriptions of OpenAI's pipeline. One folds effort into RLVR by applying different length penalties for different system prompts, such as a heavy penalty under low effort and little or none under high. The other adds an SFT stage after core RLVR in which prompts are paired with target responses of the desired reasoning length, whether human-written, model-generated or filtered. The author suspects gpt-oss and GPT-5.6 combine both.
Why it matters: developers selecting effort levels are effectively choosing a point on a cost-versus-quality curve, so the highest setting is not automatically the right default. Teams building their own reasoning models can treat effort as a training-time property that needs deliberate conditioning, not just a prompt string bolted onto an existing checkpoint. Expect UI menus, API parameters and system-prompt conventions to keep multiplying across vendors, which makes benchmarking at matched budgets more important than comparing headline scores. That inference follows from the scaling evidence described, and the underlying training methods for closed models remain undisclosed.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
How LLMs Learn Low-, Medium-, and High-Effort Reasoning Modes