NVIDIA DGX Spark Developer Kit Turns a Desk Into a Supercomputing Lab
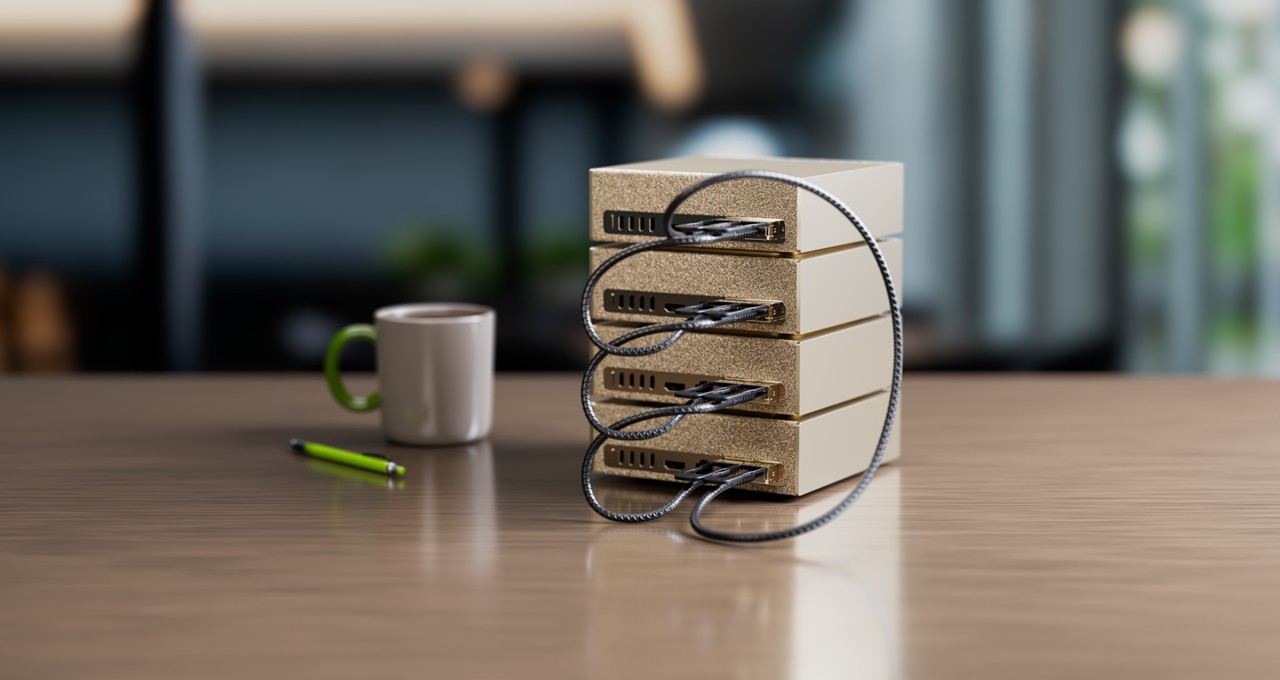
At SC26, the supercomputing conference held this week in Chicago, NVIDIA introduced the DGX Spark HPC Developer Kit, aimed at researchers, academics and developers. The kit is a four-node cluster of DGX Spark systems, built on the GB10 Grace Blackwell Superchip, with each node wired directly to its two neighbors in a ring topology. The hardware is on display at the show and is available for sale.
The central design choice is that the cluster needs no network switch. Nodes talk to each other over NVIDIA ConnectX-7 networking, and the system scales from a single node up to four. At full size, the four nodes offer 512GB of combined memory and 20TB of NVMe storage, which is the capacity researchers use to spread models and scientific workloads across the cluster.
The memory figure matters for model work. NVIDIA says that with NVFP4, a low-precision numerical format, researchers can deploy models with up to 700 billion parameters locally across the four-node cluster, naming DeepSeek V4.1 as an example. Fitting a model of that class into roughly half a terabyte of aggregate memory depends on aggressive quantization; in practice that trades some numerical fidelity for the ability to keep weights on premises rather than on a shared data-center allocation.
The pitch is about queue time and data control as much as raw compute. Researchers on fixed compute and server allocations often wait for shared GPU clusters to free up. With the kit on a desk, teams can develop and debug locally, reserving server hours for production runs, and can keep unpublished results and proprietary datasets inside their own facilities. That last point is a common driver for local hardware in industry labs and in institutions with sensitive data.
Software support is split between what ships now and what is announced as coming. An NVIDIA playbook for the HPC SDK is described as coming soon. When it lands, it is meant to bring GPU-accelerated C, C++ and Fortran compilers, libraries and message passing interface tools to the cluster — the same class of tooling used on NVIDIA-powered supercomputers. MPI is the long-standing standard for passing messages between processes on different nodes, so its presence is what makes a four-node desktop setup useful for code written for larger machines. Developers can then test scientific applications across four nodes, inspect how computation and data are distributed, and catch communication bugs before moving to bigger systems.
NVIDIA points to demonstrated four-system workloads including LAMMPS with Kokkos for materials simulation and NAMD for molecular dynamics. It also cites community validation of other codes on DGX Spark more broadly: GROMACS for molecular dynamics, OpenFOAM for fluid dynamics, WRF for weather modeling, and NIM microservices such as OpenFold3 and Boltz-2 for predicting biomolecular structures. New open dataset and post-training recipes for Nemotron 3.5 Super VL are described as helping researchers adapt that model for life sciences and chemistry on infrastructure the organization controls.
Several usage patterns are sketched out. One is agent-assisted workflows that prepare simulation inputs, launch runs and summarize results, with scientists validating the setup and conclusions. Another is training surrogate AI models that approximate slow simulations and then using them to refine wing designs toward minimum drag. A third is narrowing a ten-million-cell simulation down to the 50 to 500 dimensions that actually matter before spending supercomputer time.
NVIDIA cites several groups already working on the hardware. Kvantify, using NVIDIA cuQuantum, reports tensor-network simulations of quantum-chemistry circuits with up to 70 qubits and 975 gates on a single DGX Spark, benchmarking circuits generated for penicillin ground-state energy calculations. CYRAN AI, an IIT Delhi spin-out, uses DGX Spark and its PixelFlux library to speed JPEG 2000 decoding for large satellite images in support of local geospatial analysis. OpenFold demonstrates fine-tuning OpenFold3 on a single DGX Spark to improve protein-ligand structure predictions for drug discovery.
The Rubin Lab at IGI at the University of California, Berkeley, is using a DGX Spark with the NVIDIA Evo 2 model to predict bacterial traits directly from genome sequences, comparing embeddings from genomic and protein language models against classical baselines; NVIDIA says results arrived 15 times sooner than with 11-hour cluster queue times. The Hartwig Group at UC Berkeley is doing LoRA fine-tuning of the Nemotron 3 Super 120B-A12B model for chemistry machine learning, training a prediction head on experimental values. Running locally with NVFP4 quantization, the lab fit a 120B-class model on a single device, skipped multi-day cluster queues, and now runs continuous eight- to 24-hour training fits back to back.
Availability runs through OEM partners and the NVIDIA Marketplace, with DGX Spark products and cables sold by Acer, ASUS, Dell Technologies, GIGABYTE, H3C, HP, Lenovo, MSI and xFusion. A second playbook, covering building and running the HPC SDK, is promised soon; it is positioned as a local platform for developing multi-node GPU applications, exploring FP32 and mixed-precision algorithms, and running molecular dynamics and materials simulations with LAMMPS and Kokkos before scaling to data-center systems.
A reasonable reading is that the kit is a development and prototyping tier rather than a replacement for a supercomputer. Four nodes in a ring are enough to shake out MPI decomposition and communication problems, but the interconnect topology and node count are far smaller than a data-center fabric, so scaling behavior will not transfer perfectly. The dependence on NVFP4 for the largest models also means teams should check accuracy against their own workloads before committing. Pricing was not disclosed in the announcement.
Why it matters: Academic and industry labs that compete for shared GPU time gain a way to iterate locally and keep sensitive data on site, which could shorten the loop between experiment and result. For developers, the value hinges on the promised HPC SDK playbook, since without MPI and compiled-language tooling the cluster is mainly an AI inference box. Teams evaluating the kit should test their own codes at four nodes and weigh quantization accuracy before treating desktop results as predictive of data-center runs — an inference from the stated specs rather than a claim NVIDIA makes.
Based on reporting from the original publisher. Visit the source for full context and later updates.
Publisher excerpt
At SC26, an annual supercomputing conference taking place this week in Chicago, NVIDIA is introducing the DGX Spark HPC Developer Kit for researchers, academics and developers. The kit is a four-node cluster of NVIDIA DGX Spark systems, each connected directly to its two neighbors in a ring, with an NVIDIA HPC SDK installation playbook coming […]